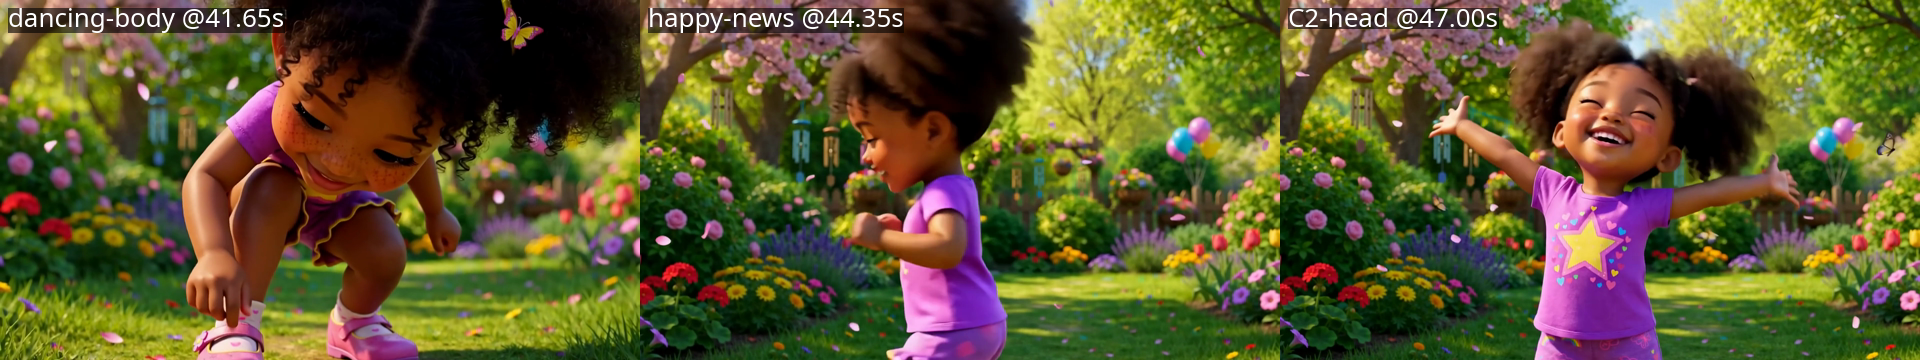Same shots as v1 (the look is approved) — this pass is EDIT ONLY. Every action in 0:00–0:48 was re-audited against the word map and re-timed with a per-clip piecewise warp so each touch / point / pat / count lands ON its sung word. Fixed: Clip B's 1-2-3 finger count (was ~2s early — now 1, 2, 3 land on their words), Clip D's head pat (was trimmed out of v1 entirely — now in, on "head"), Clip D's mouth/nose points, Clip C's shoulders/knees/toes chain (was up to ~2.2s early), Clip E's shoulders/knees (was up to ~3.6s early), Clip F's toes/shoes/dance beats. One honest flag: Clip D has no shoulders pat in the footage — she holds a hand on her chest there — so the chest-hold is centered on the "shoulders" word; a true shoulders pat needs a wave-2 regeneration of that clip. Full before→after offset table: BUILD-NOTES-wave1-v2.md. Wave 2 (rest of C2, Bridge, Final Chorus) still pending the fal.ai top-up.